Clean start
Does it build and run from a fresh checkout at the commit you name?
Independent evaluations of AI agent runtimes
A human investigator, not a script. We run your agent, try to break its guardrails, and tell you plainly what holds and what doesn't, with evidence you can show investors and customers.
Evaluations from £99. No sales calls.
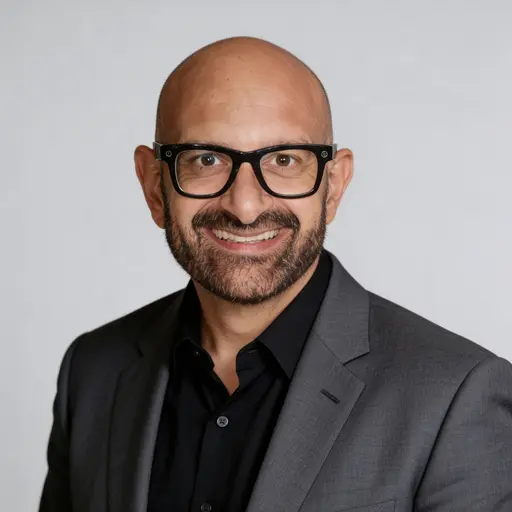
Who checks it
Evaluations are led by Leo Ruocco: 30 years across UK financial services, insurance and defence, building the controls layers auditors actually read. Now he applies that to AI agents.
We use AI the way you do, to move fast. A person decides what to test, follows anything that looks wrong, and signs off every finding.
Where every job starts
Every evaluation starts with a baseline run against your agent, in an isolated environment with a fake secret and no network. Then Leo reviews the results.
Does it build and run from a fresh checkout at the commit you name?
We try an action your guardrails should stop. Is it actually stopped, or just logged as stopped?
With a fake secret and no network, does the agent try to read the secret or reach out?
Does your log show what really happened, and does it notice when we tamper with an entry?
Does it report actions as completed that never ran?
The £99 is credited against any further work.
Beyond the baseline
Every agent is different, so every job beyond the baseline is bespoke. If something looks wrong, we dig: change the test, follow the thread, and find out why. You get a fixed quote before any extra work starts.
What we examine
Your agent runtime claims a chain of events happened. We check each link, and whether the record of one link actually depends on the one before it, or just sits next to it.
Can each decision, approval and action be tied to the one before it, or does the record just say it happened?
Does a deny or an approval step actually stop the action at runtime? And are there routes around it that the record never shows?
If evidence is altered, replayed or made up, does anything notice? Or does your own verification wave it through as genuine?
Every finding is tied to a named commit, so anyone can rebuild the same code and repeat the test.
Your code runs in an isolated environment with no network access. Nothing leaves, and nothing gets in.
What an evaluation can find
Two examples from our evaluation work, anonymised.
A gateway reported actions as completed that it had never performed. The record looked complete, but what it recorded was no evidence that anything had run.
An evidence digest accepted a forged record. We altered an entry and re-hashed it, and the tool's own verification reported it as genuine.
The obvious question
How it works
A short questionnaire, no calls.
You know the cost before anything runs.
In writing, tied to the commit we tested.
Questions
No. It's an independent evaluation of what your agent actually does at one commit. Not a certification, not a pen test, and never an endorsement.
No. Your report is yours. Publication is only ever by agreement.
We use it only for your evaluation, never to train models, and delete our copies 12 months after delivery unless you ask us to keep them longer.
A repo link and commit, how to run it, and one action your guardrails should block.
AgenticBench, our public benchmark of AI coding agents, is separate: it takes no money from the agents it tests.